

Writing from the
cedana team.


insights from the team.
Field reports, engineering deep-dives, and benchmarks from the Cedana team.
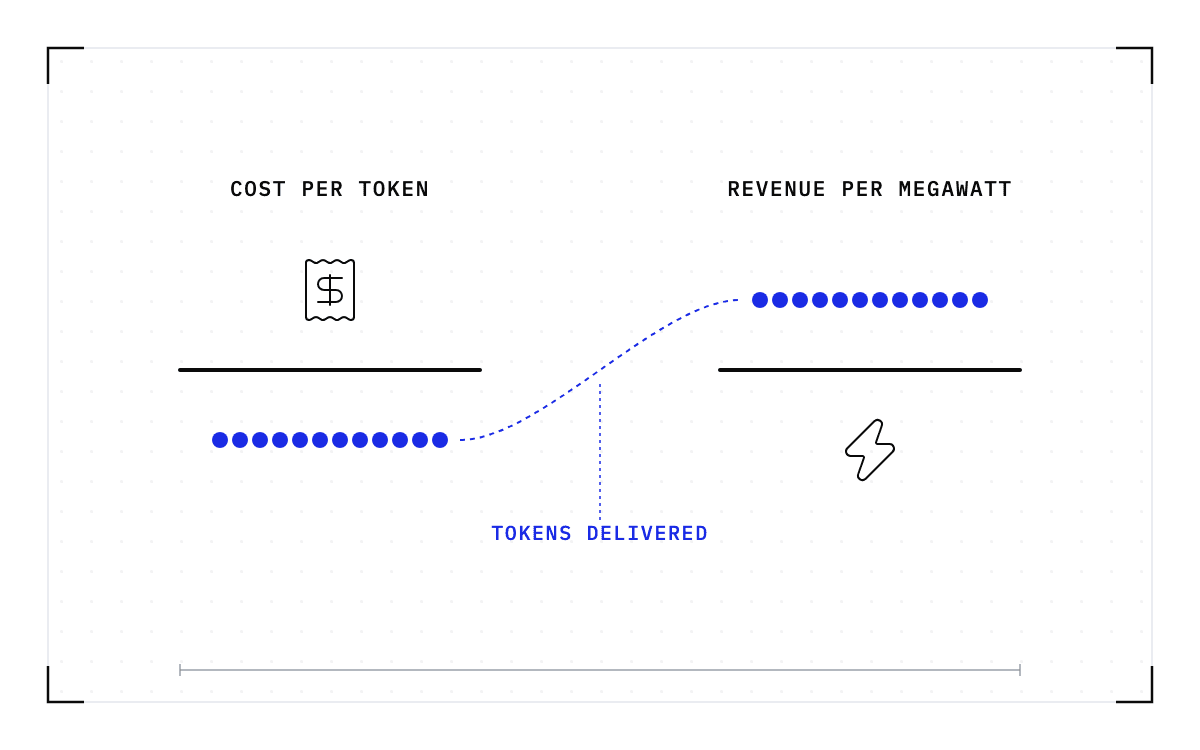
Cost per token and revenue per megawatt are the same number
Calculate cost per delivered token from fleet costs and serving logs, then see how cold starts, failures and stranded capacity also affect revenue per megawatt.
read →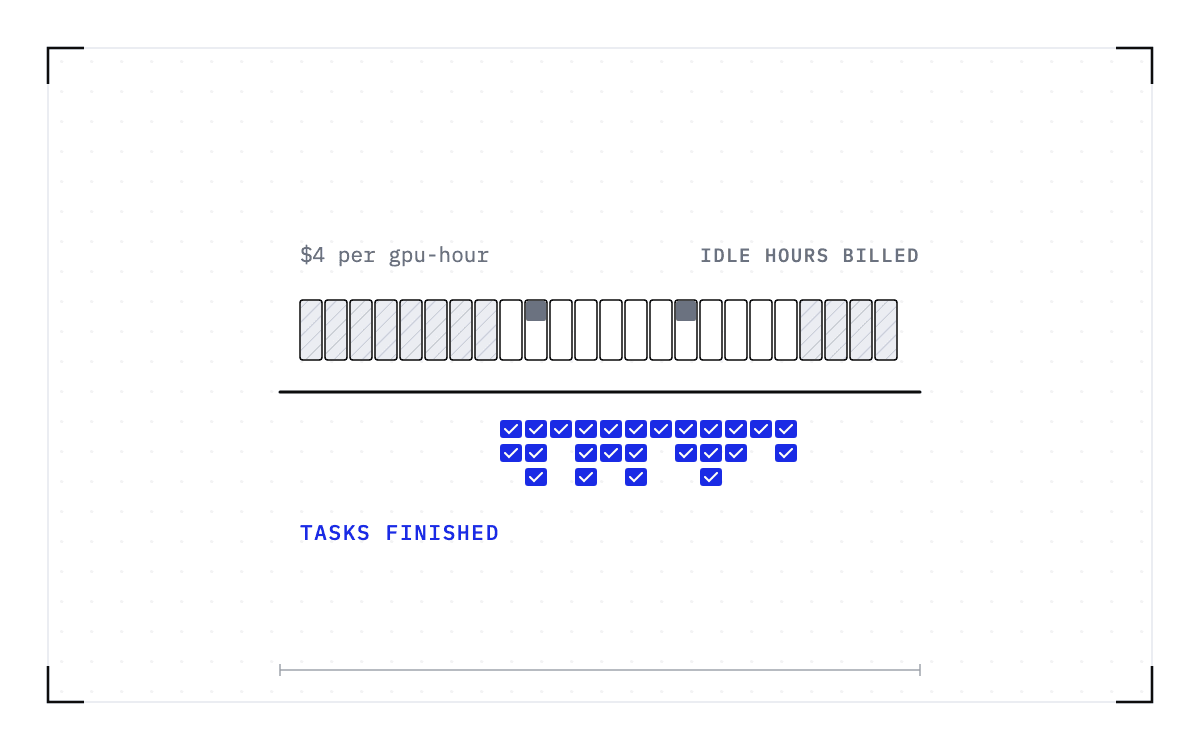
Tasks per dollar: the economics of running your own coding models
Compare coding APIs and self-hosted GPUs using cost per completed task. Account for idle node hours, model swaps and task completion on your own traffic.
read →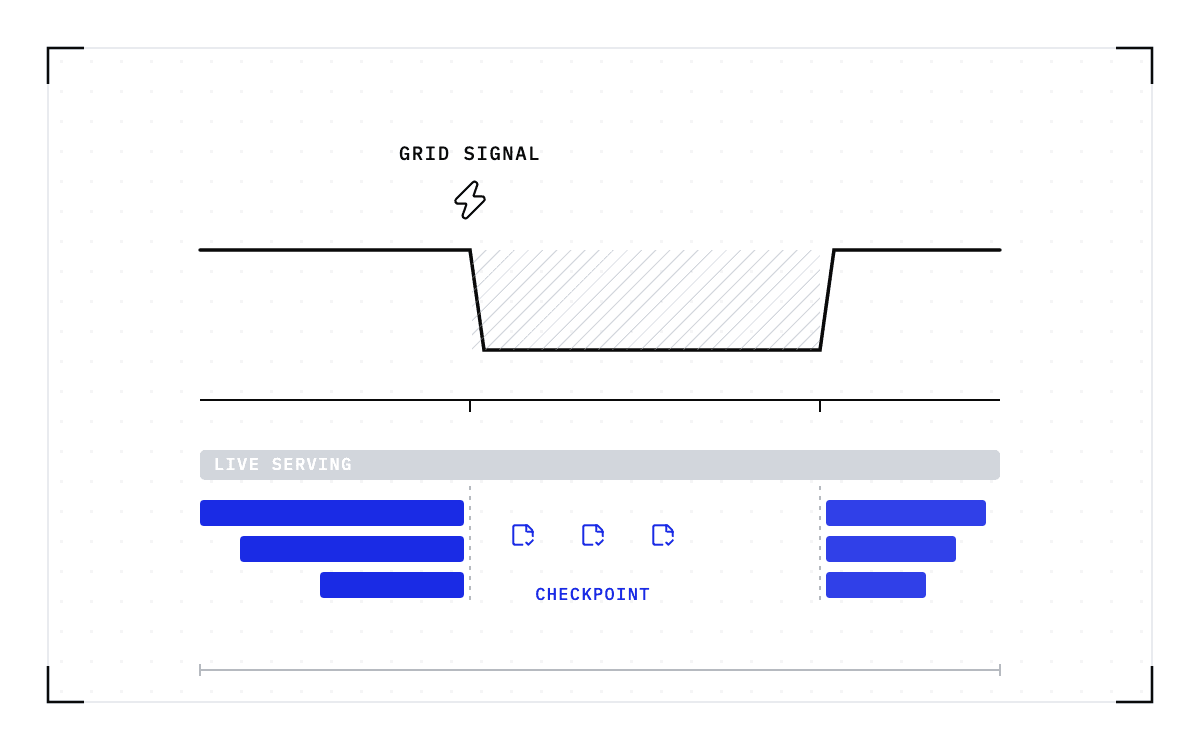
Demand response for GPU fleets: what the programs require
Review two GPU demand response trials, the workloads they could flex, and why deeper power cuts require saved job state. Separate trial results from design targets.
read →
Sovereignty has a bill: the transferred duties and the availability math
Size the availability responsibilities of running inference on your own hardware, including spare capacity, recovery time and a single node's outage allowance.
read →
How much utilization improvement do you need to break even on GPU checkpointing?
Calculate the utilization gain needed to cover a GPU checkpointing fee using your operating cost, paid hours, restore cost and recoverable work.
read →
Which utilization number goes into your own-versus-rent calculation?
Compare owning GPUs, renting nodes and paying per token using delivered GPU-hours, operating costs and utilization instead of demand forecasts alone.
read →
How to put a dollar figure on the GPU-hours that produced nothing
Calculate the cost of idle GPUs, cold starts and recompute using your own hourly rate. Separate paid busy time from work your fleet actually keeps.
read →Showing 7 of 7 posts