Writing from the
cedana team.
insights from the team.
Field reports, engineering deep-dives, and benchmarks from the Cedana team.
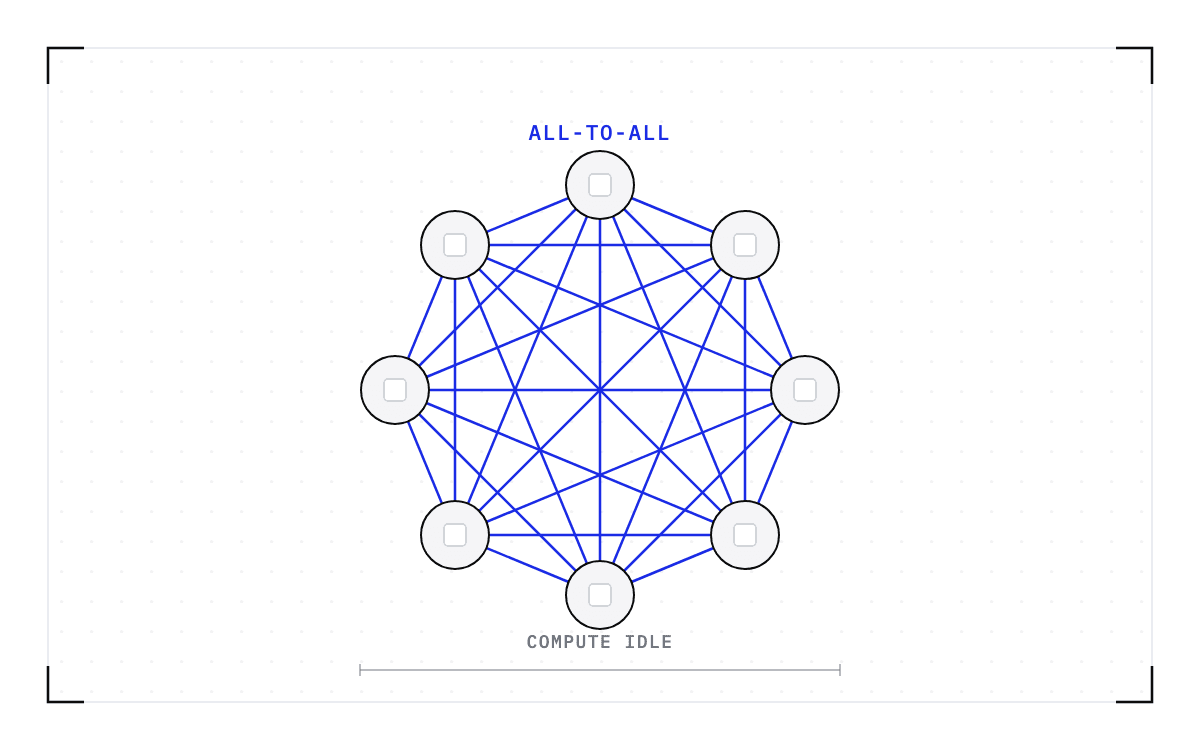

MoE serving is a network problem, and more GPUs will not fix it
Diagnose compute, memory and interconnect limits in MoE inference. See why activated parameter counts and extra GPUs cannot replace communication measurements.
read →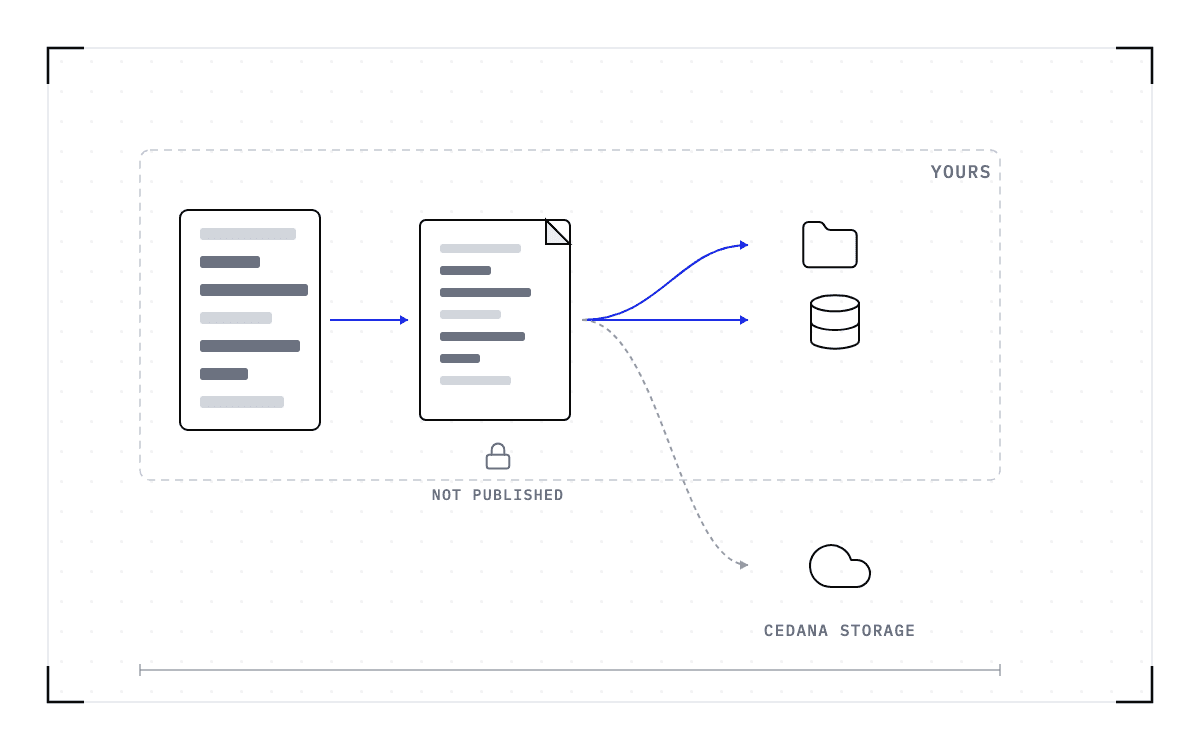

Where checkpoints live, how long they stay, and who can read them
Choose where GPU checkpoints live, how long they remain and who can read them. Identify the encryption and key-management answers a security review still needs.
read →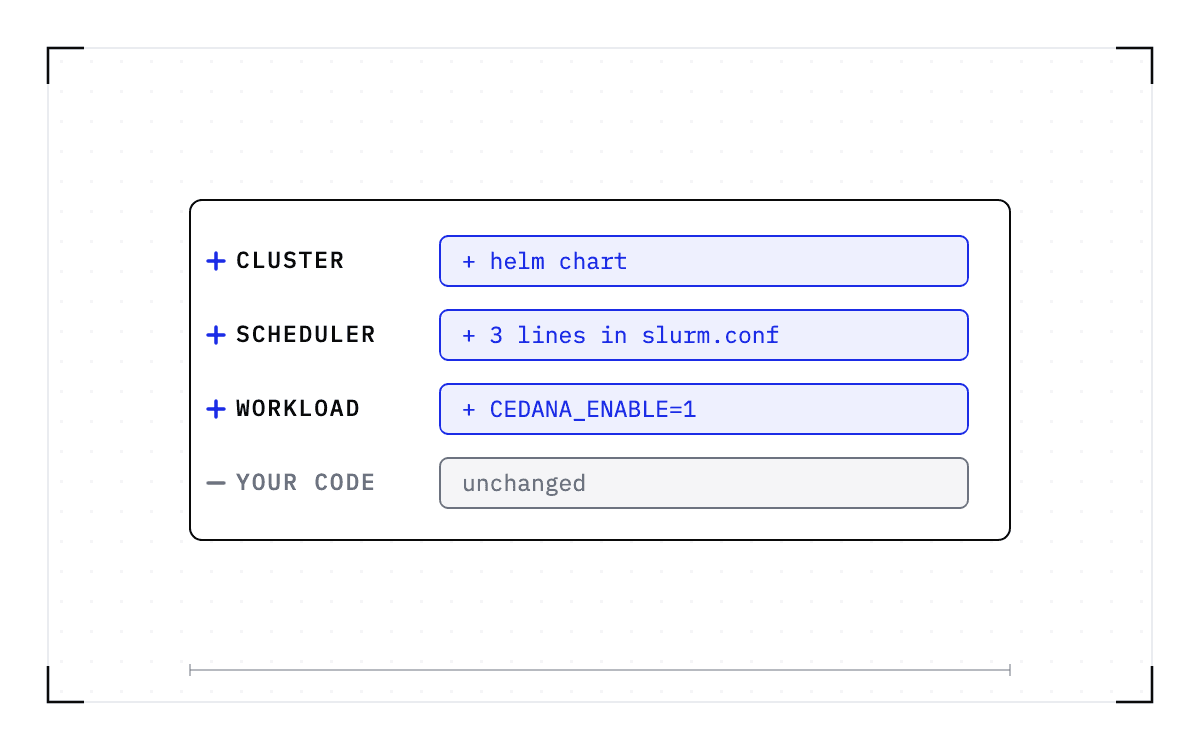

What actually changes on my cluster when I install Cedana?
Review the Helm install, Slurm plugins and workload opt-in settings Cedana adds to a cluster, with configuration examples and the application-code boundary.
read →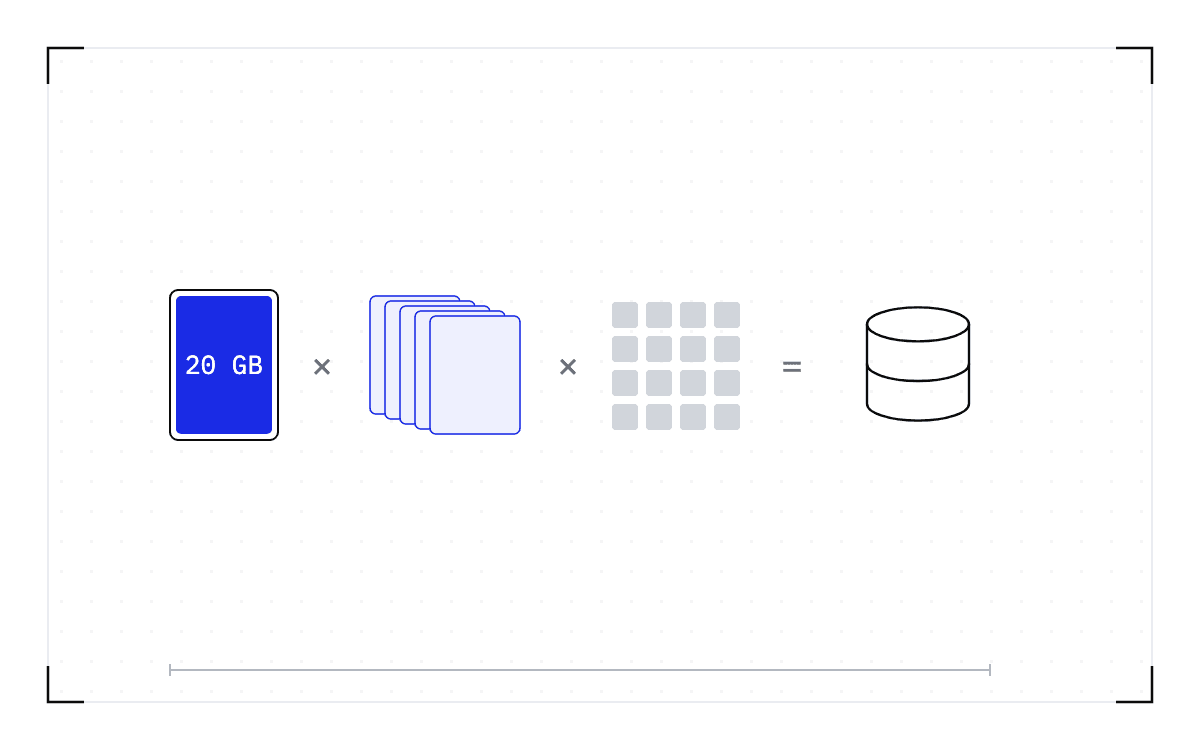

How much storage does checkpointing a GPU cluster need?
Estimate checkpoint storage from workload memory, retained copies and job count. Review quota controls, storage bandwidth and unanswered lifecycle behaviors.
read →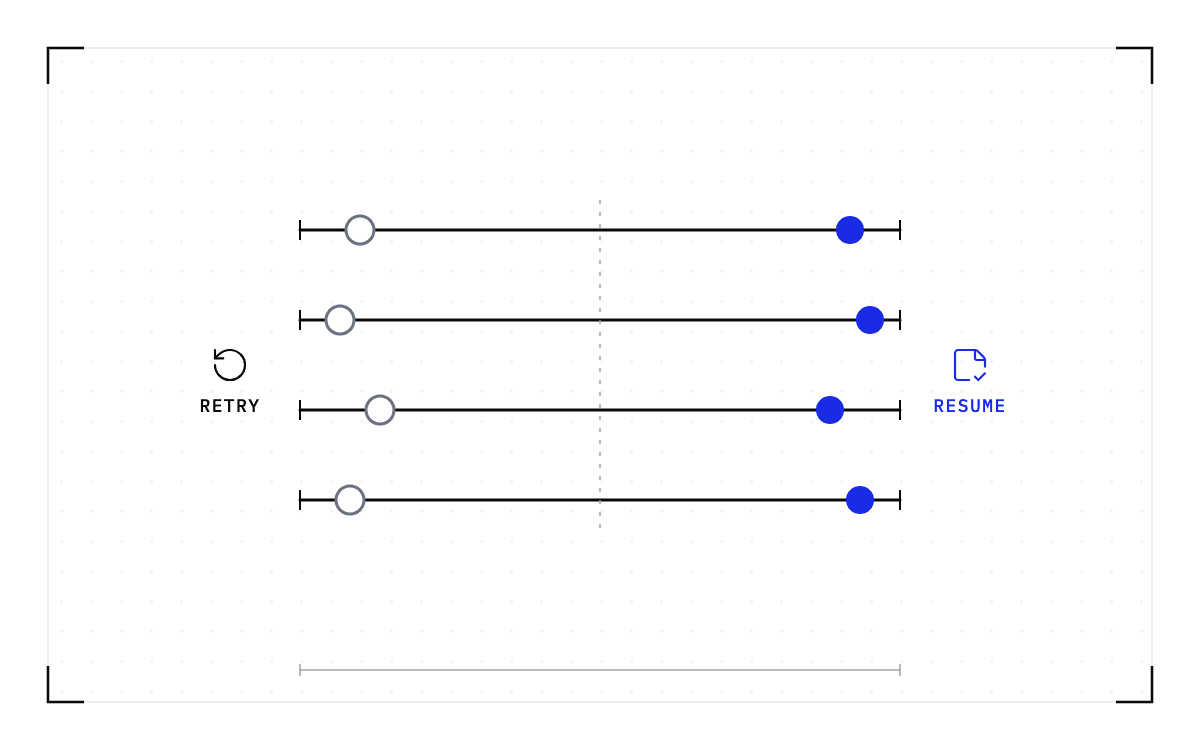

When retrying the job is the right call
Decide whether a GPU job needs checkpoints using interruption risk, work at stake, rebuild cost and deadline slack. Keep application idempotency in either path.
read →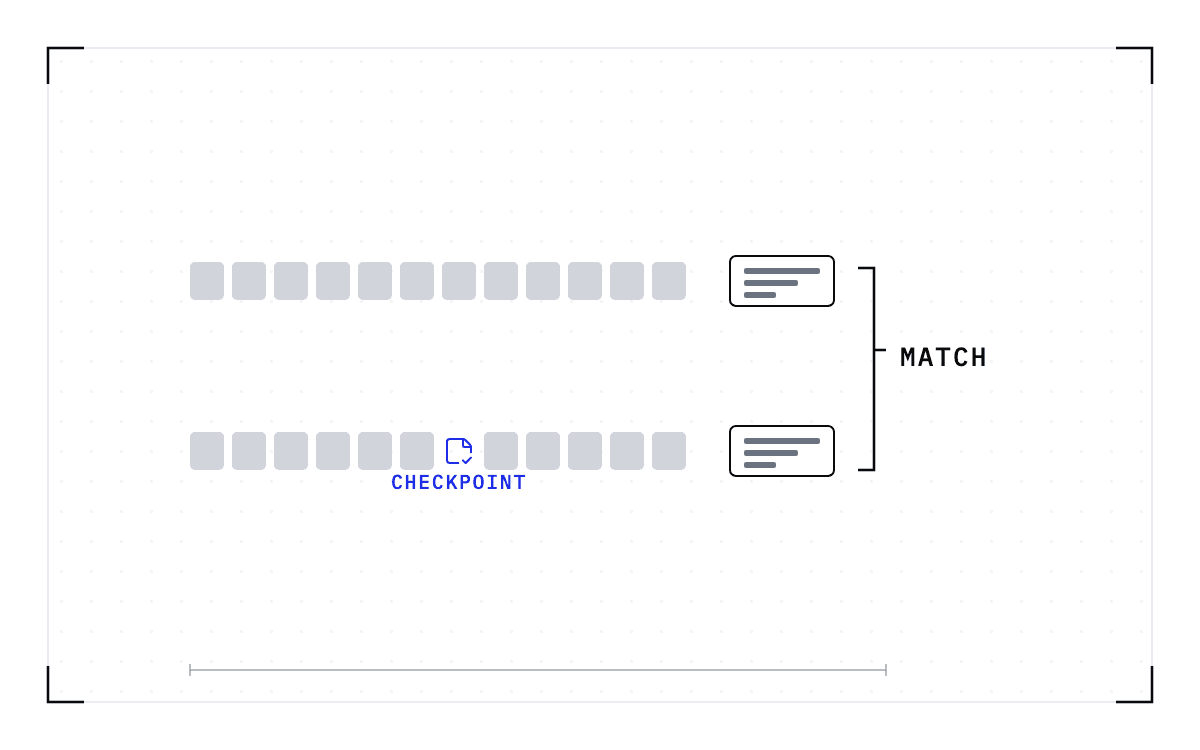

How to know a restored GPU workload is correct
Test whether a restored GPU workload continues the same computation. Compare repeatable runs, check multi-GPU boundaries and record the exact environment.
read →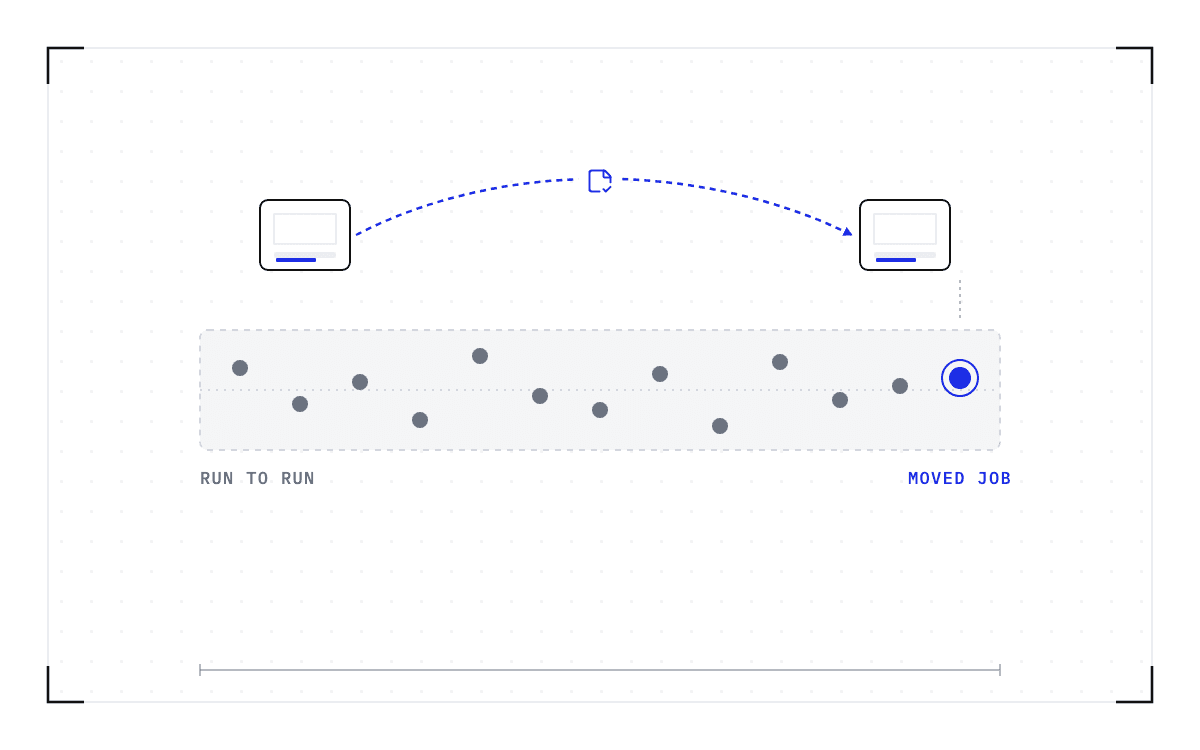

Does moving a job change its results?
Understand what a checkpoint preserves when a GPU job moves, which versions must match, and how live inputs and ordinary GPU variation affect reproducibility.
read →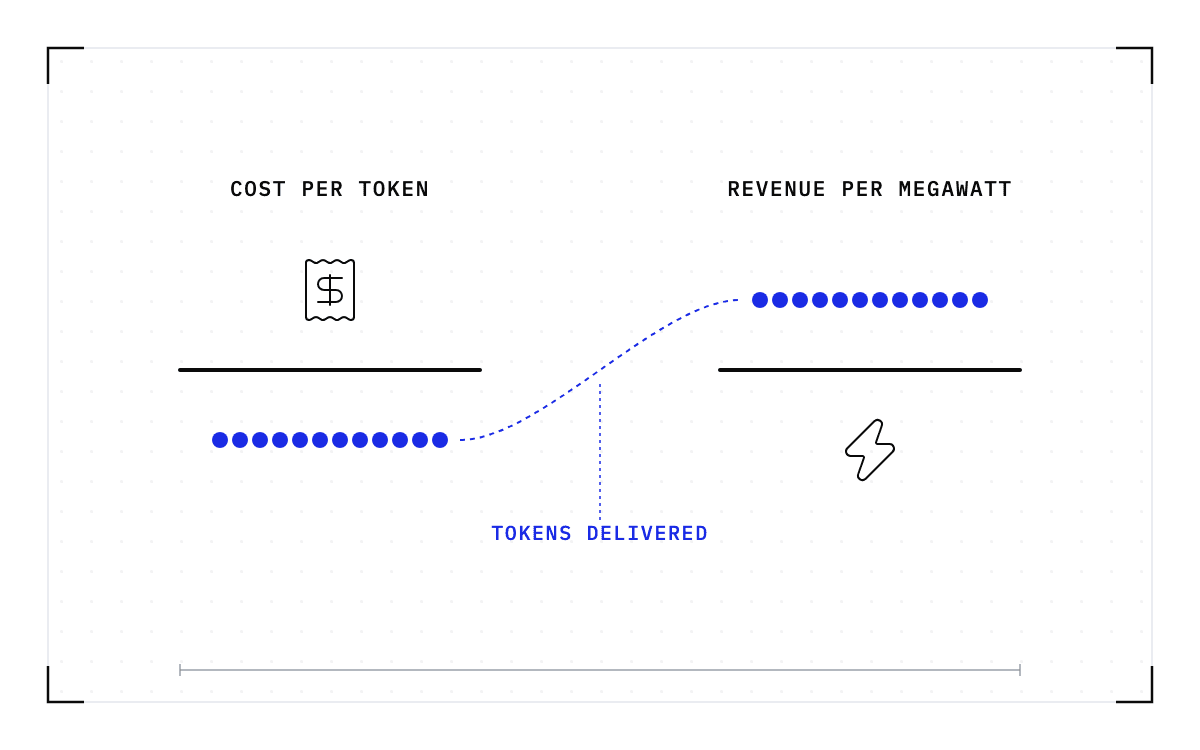

Cost per token and revenue per megawatt are the same number
Calculate cost per delivered token from fleet costs and serving logs, then see how cold starts, failures and stranded capacity also affect revenue per megawatt.
read →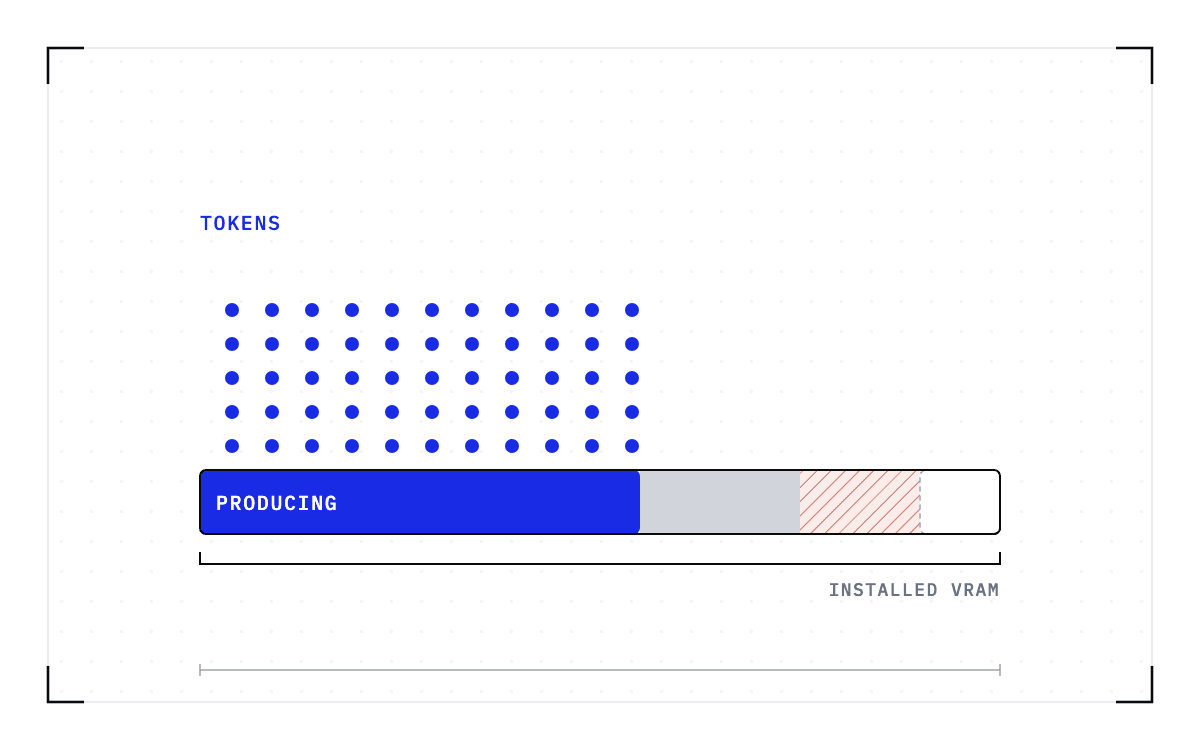

The fleet's real yield metric is tokens per gigabyte of VRAM
Measure delivered tokens against installed VRAM. See how memory bandwidth, warm replicas, failures and stranded GPUs affect the output of an inference fleet.
read →

KV-cache offload versus a saved worker: what each survives
Compare the state preserved by KV-cache offload and a full worker checkpoint. Learn what survives a crash, what must reload, and where prefix reuse still helps.
read →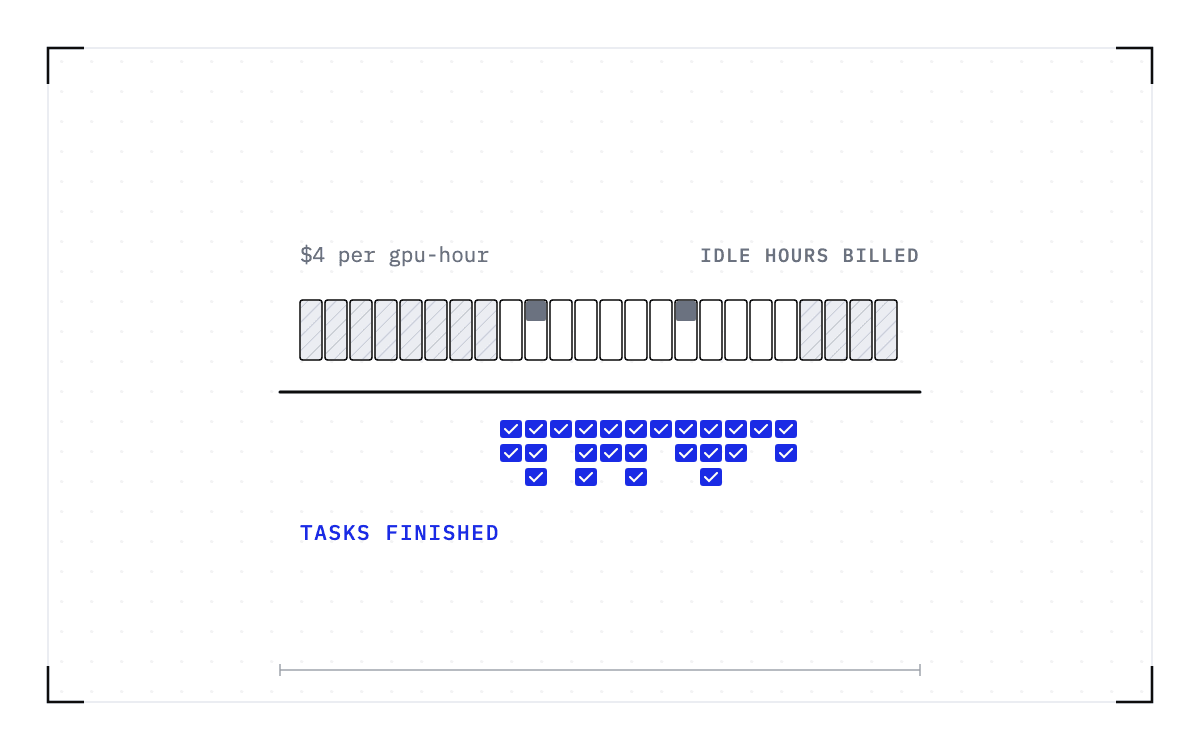

Tasks per dollar: the economics of running your own coding models
Compare coding APIs and self-hosted GPUs using cost per completed task. Account for idle node hours, model swaps and task completion on your own traffic.
read →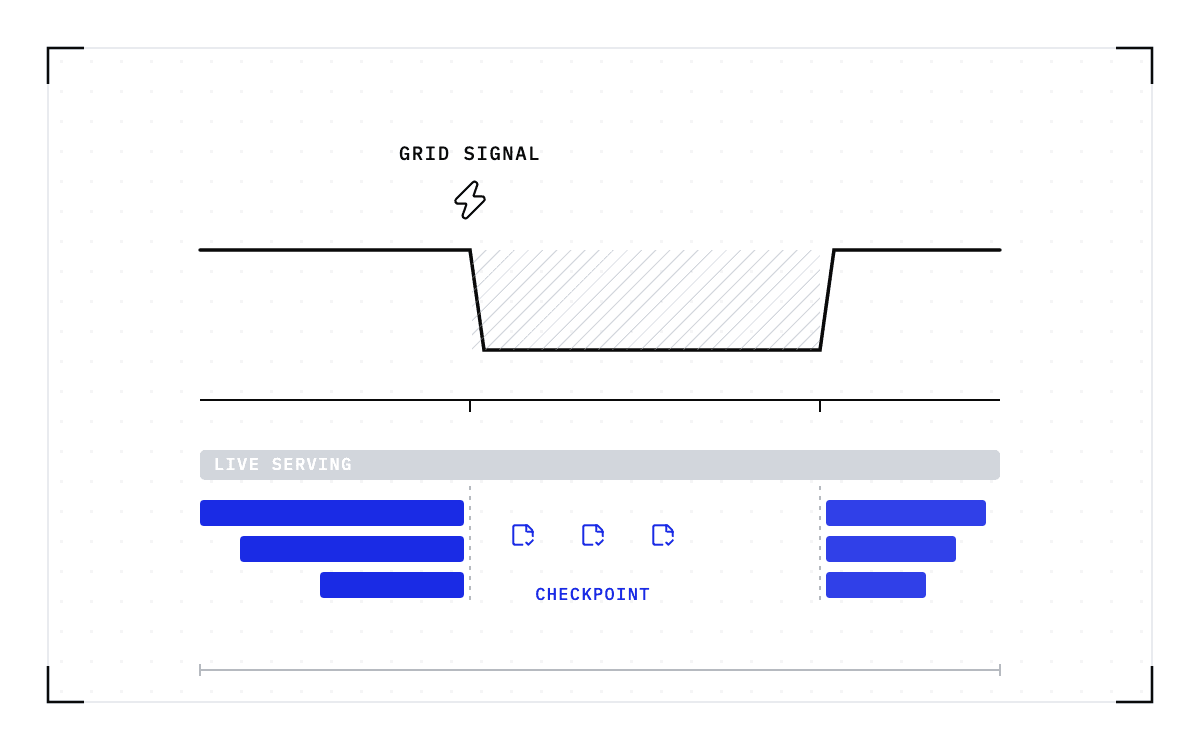

Demand response for GPU fleets: what the programs require
Review two GPU demand response trials, the workloads they could flex, and why deeper power cuts require saved job state. Separate trial results from design targets.
read →Showing 13–24 of 99 posts