Writing from the
cedana team.
insights from the team.
Field reports, engineering deep-dives, and benchmarks from the Cedana team.
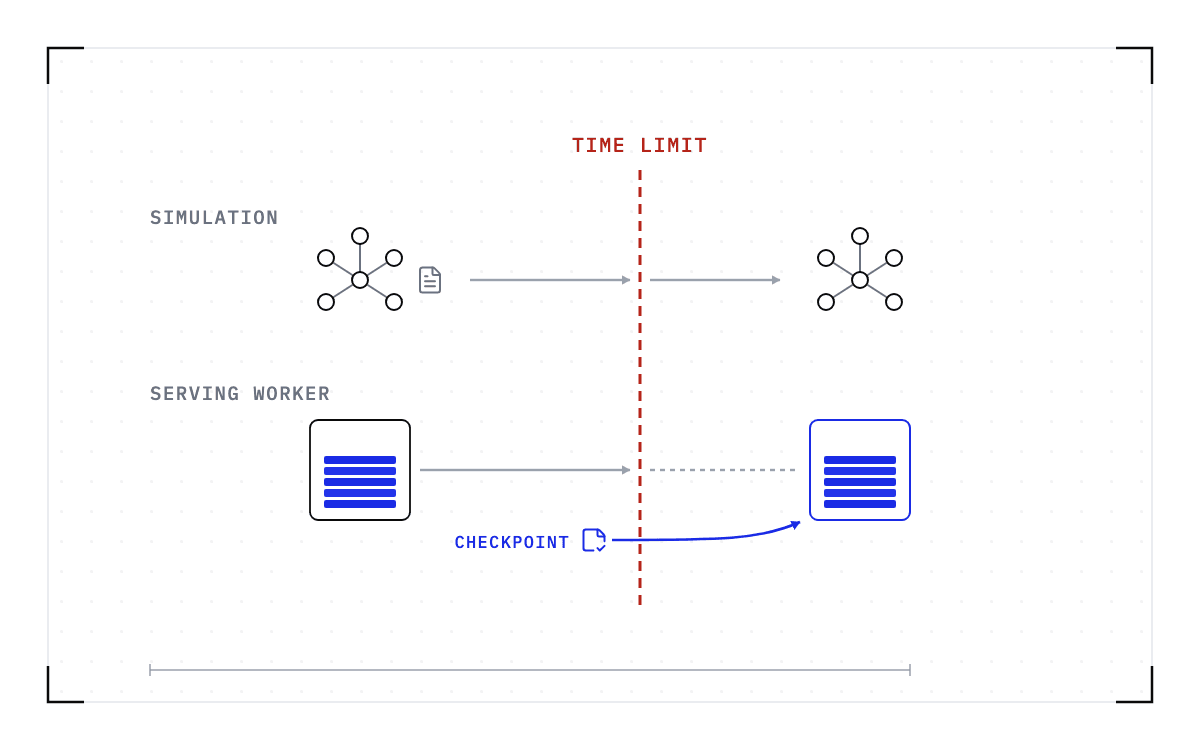

Stateful AI has the same boundary problem as long HPC runs
See why inference, fine-tuning and agent workloads face the same allocation limits as HPC simulations, but carry different state and recovery obligations.
read →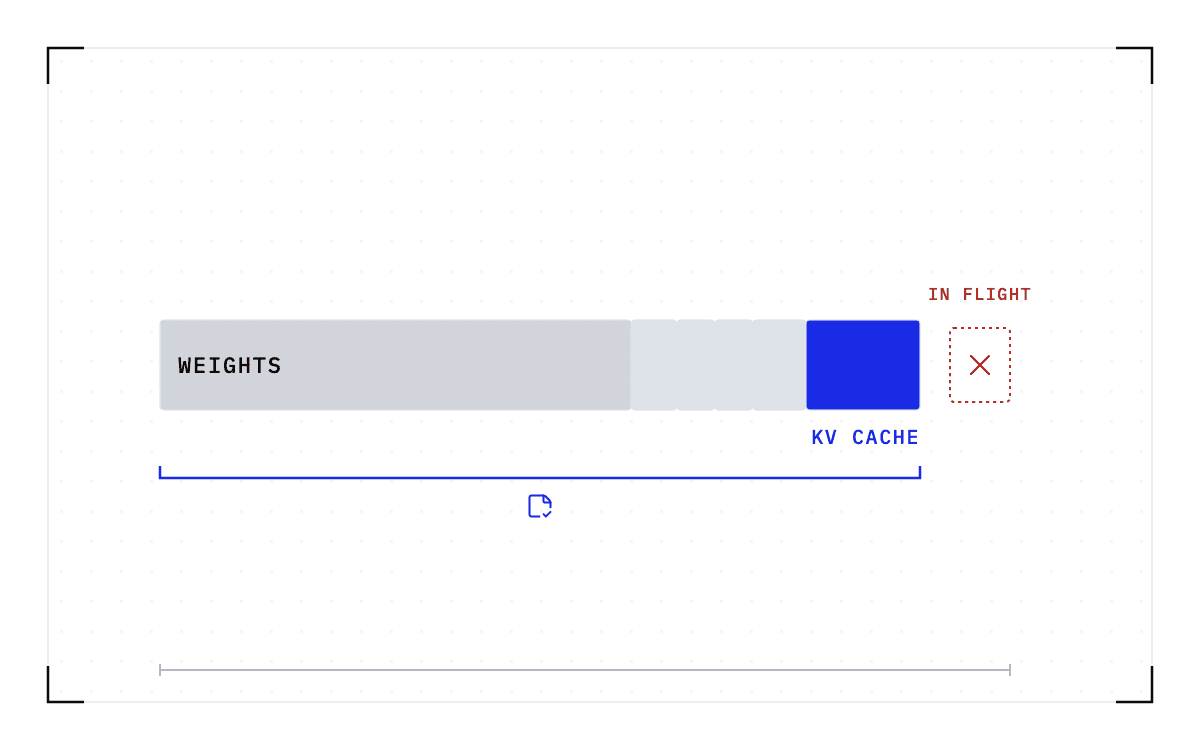

What is inside a GPU checkpoint?
See the weights, KV cache, CUDA context and process state inside a GPU checkpoint, how they affect its size, and what a restart has to rebuild.
read →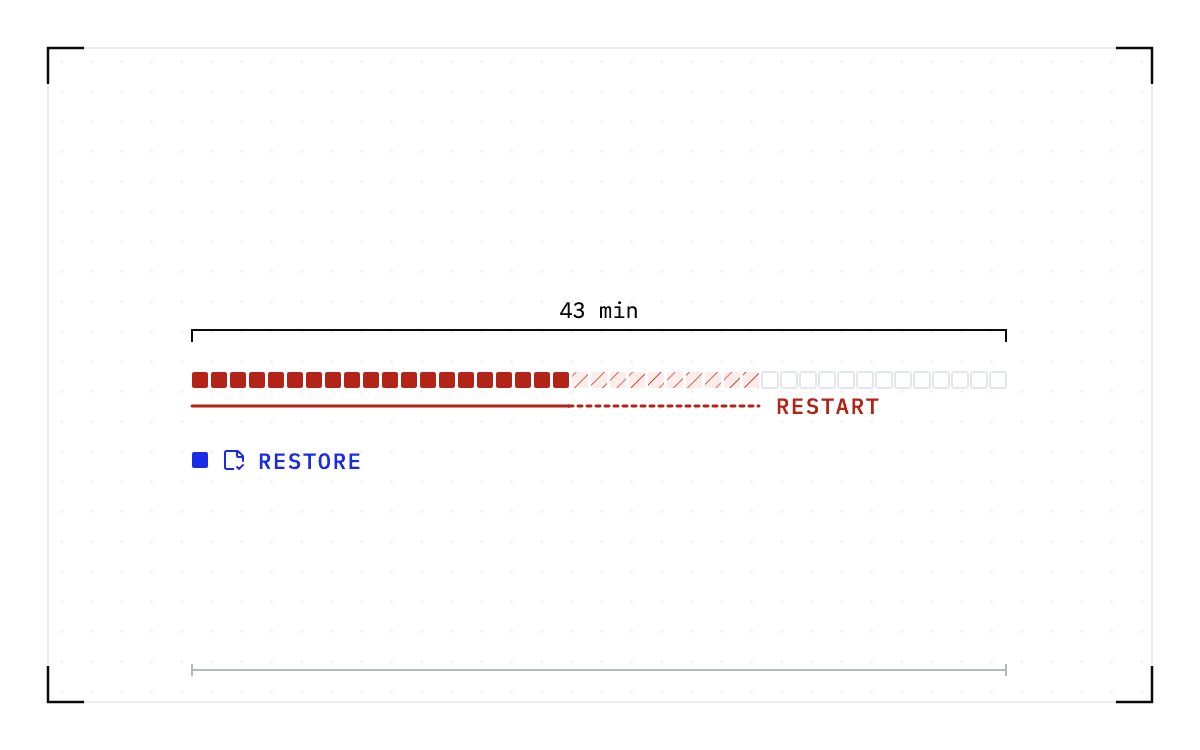

One frontier restart burns half a monthly 99.9% error budget
Calculate how model restart time consumes an inference error budget, what replicas change, and how to compare a measured restore with your availability SLO.
read →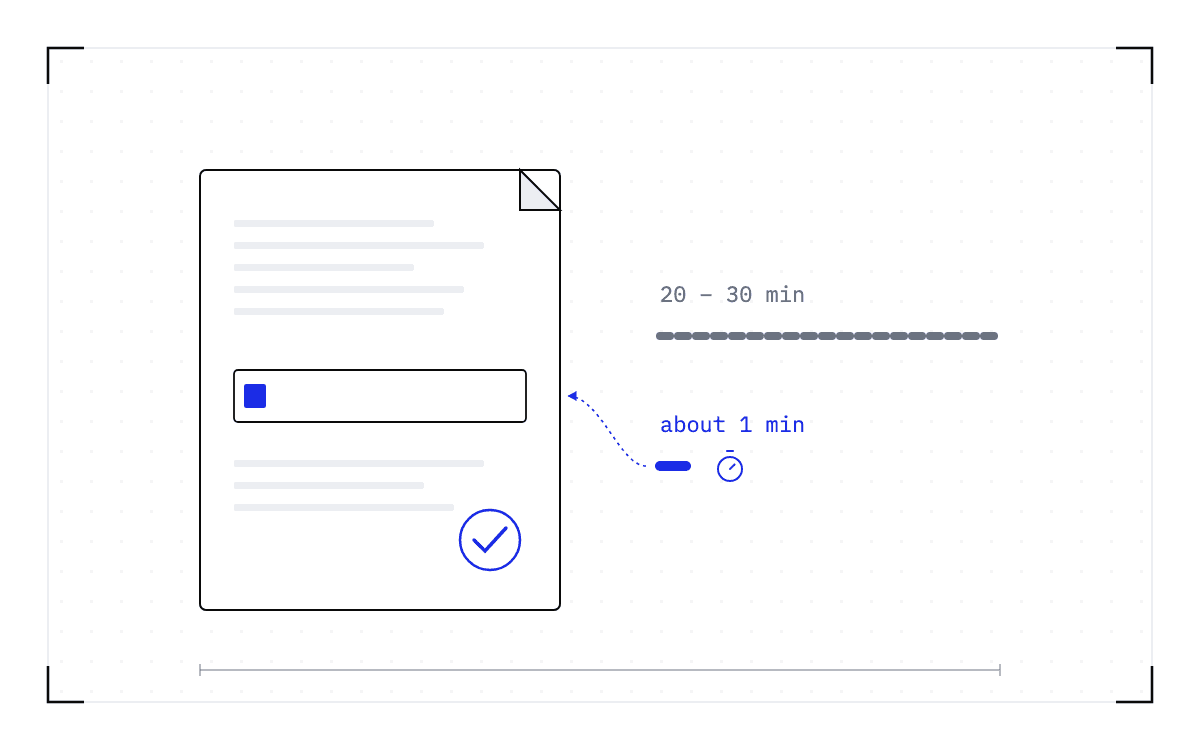

The recovery time you can put in a filing
Define and test LLM recovery time from failure to serving again. Separate restore benchmarks from the detection, placement and recovery your team must document.
read →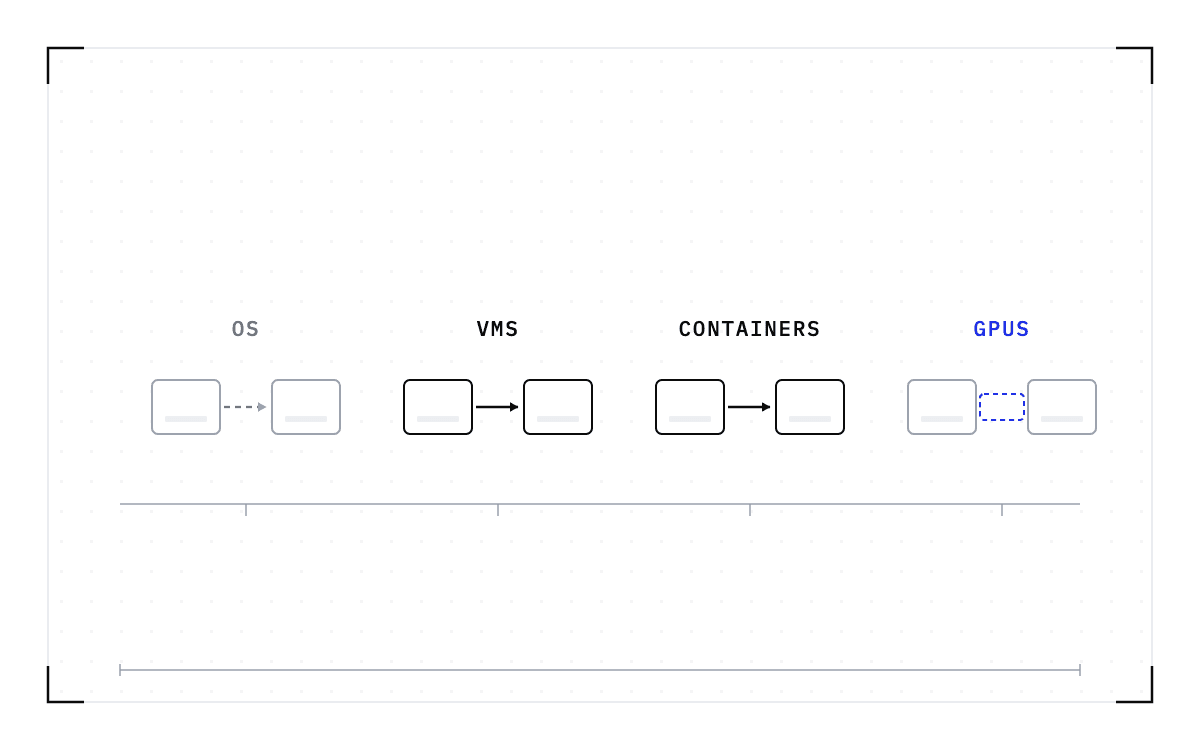

Every era of computing needed a migration primitive. GPUs are next
Trace migration through operating systems, virtual machines, containers and databases to understand why GPU fleets need portable running state.
read →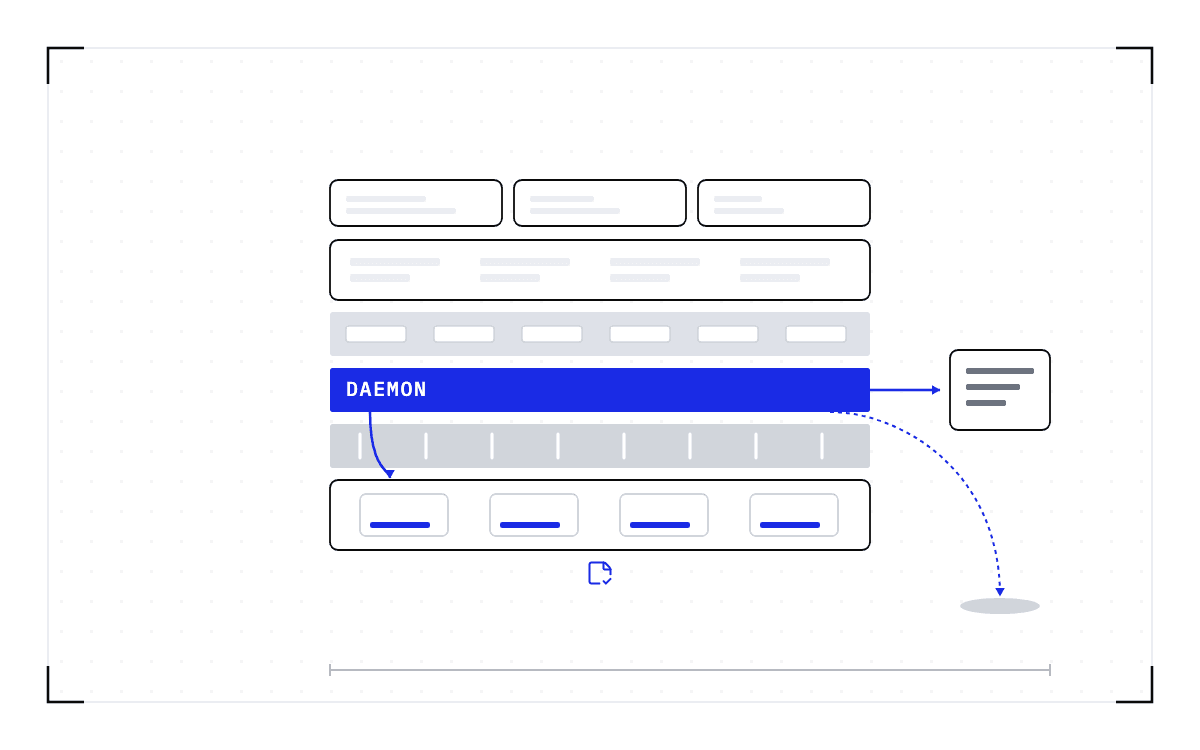

How Cedana works: checkpoint, restore, and migration below the serving engine
Explore Cedana's daemon, CRIU and GPU capture layers, the state they restore, and the policies, storage paths and compatibility limits around them.
read →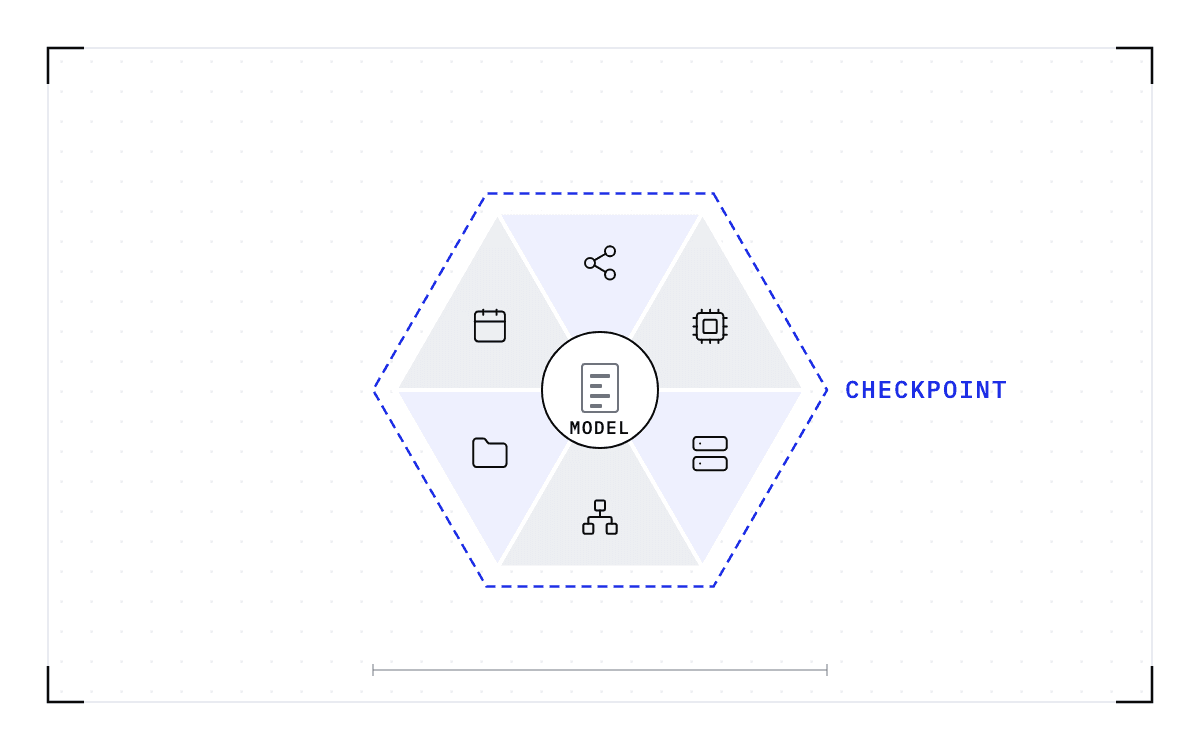

What is GPU checkpointing? A plain explanation
Learn what GPU checkpointing saves, how checkpoint, snapshot, restore and migration differ, and why saving model weights alone cannot resume a workload.
read →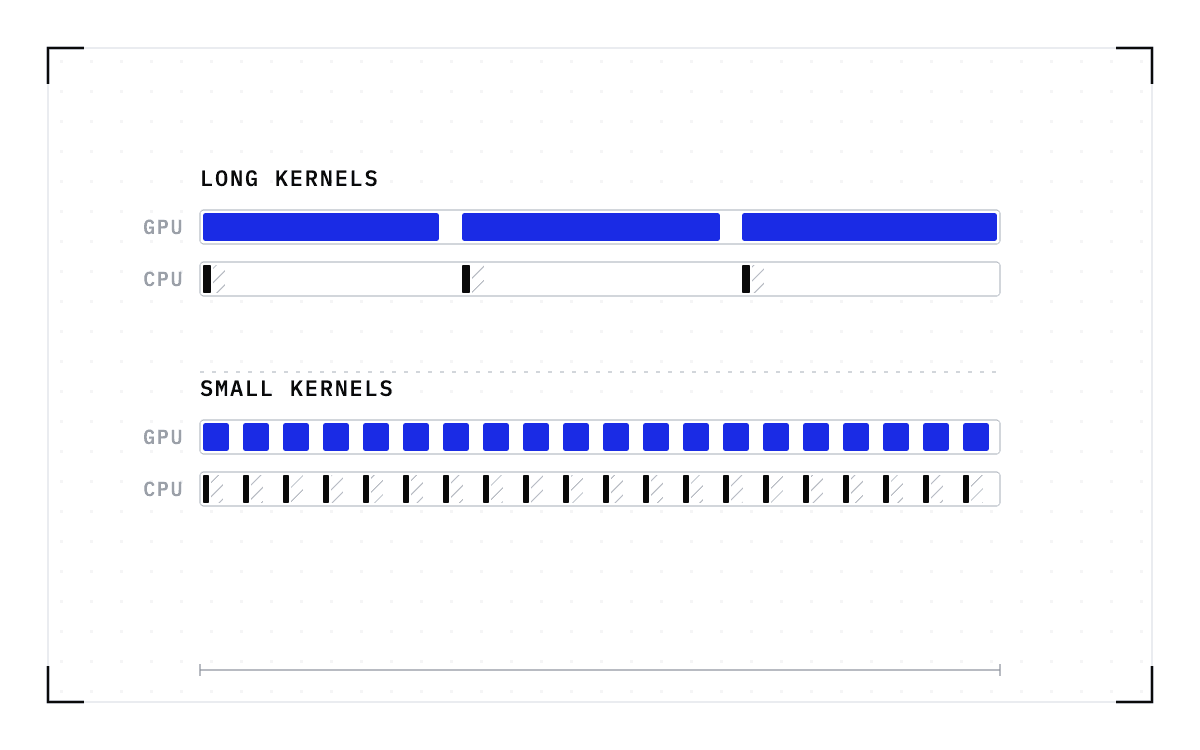

What a GPU checkpointing layer costs while the workload runs
Understand steady-state GPU checkpointing overhead, why driver-call patterns matter, and what Cedana's published single-GPU measurements leave unanswered.
read →

Which GPU workloads should I checkpoint first, and which should I leave alone?
Choose a small first workload set for GPU checkpointing. Review opt-in controls, cheap retries, real-time inputs, external side effects and untested job servers.
read →

How do I run a proof of concept for GPU checkpointing?
Plan a GPU checkpointing evaluation with a matched baseline, real interruptions, correctness checks and agreed success criteria before expanding the install.
read →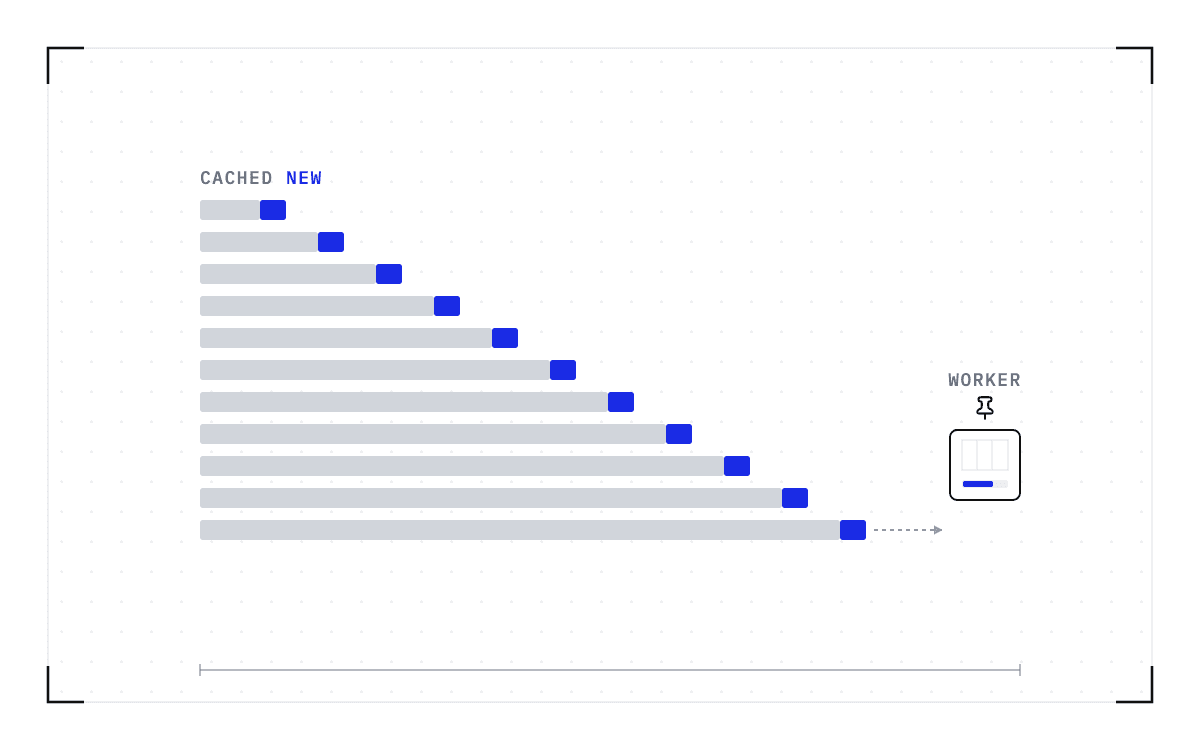

How long do agentic sessions run, and where does their state live?
Explore published coding-agent traces to see how turns, cache reuse and pauses shape session affinity, GPU memory use and the cost of a lost worker.
read →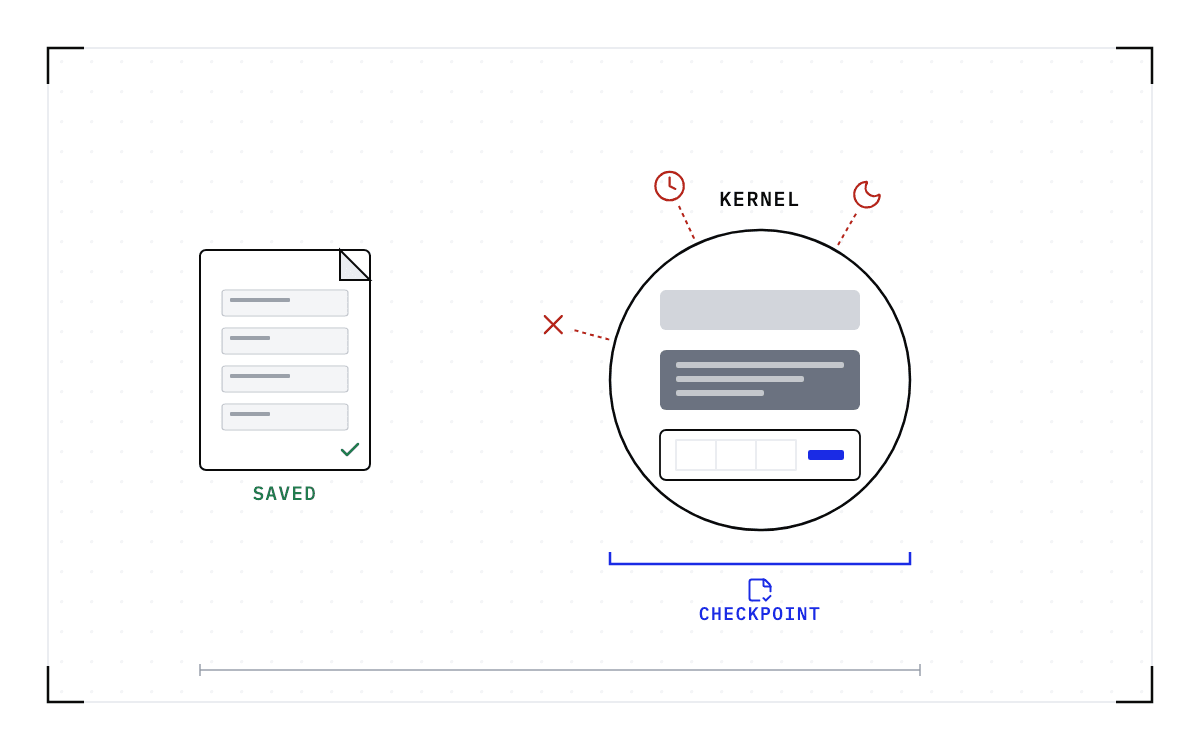

When the node dies under a Jupyter session
Learn what a notebook file cannot recover after a GPU node fails, how process checkpoints preserve kernel state, and which restoration limits still apply.
read →Showing 25–36 of 99 posts